RAG Development Services for Enterprise Knowledge AI
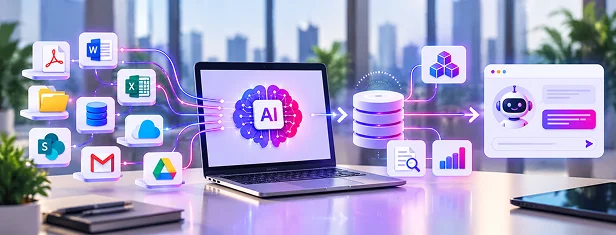
Connect your AI models to the data that runs your business. We build RAG development services that integrate private documents, databases, and enterprise systems. The result is retrieval-grounded AI applications your teams can actually trust.
- Private Data Retrieval
- Vector Search & Embeddings
- Document-Grounded Answers
- Enterprise Knowledge Assistants
What RAG Development Means for Enterprise Knowledge AI
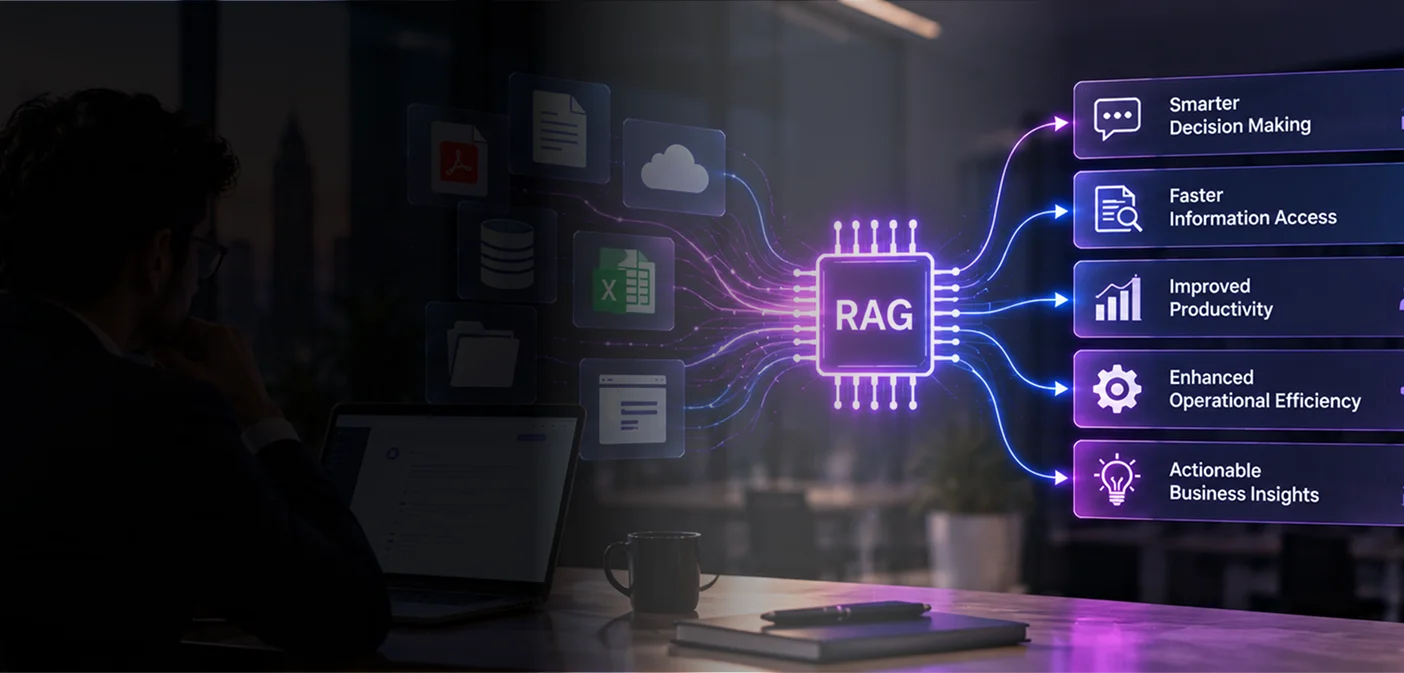
RAG connects a language model to your live data at query time, so every answer is grounded in real content.
Retrieval Augmented Generation, Explained
RAG retrieves relevant content first, then generates an answer grounded in that content. It does not rely on the model's training data alone.
RAG vs Fine-Tuning vs Prompt Engineering
Fine-tuning retrains the model and goes stale as data changes. Retrieval keeps answers current without retraining the underlying model.
Core Components of an Enterprise RAG Architecture
A production system needs ingestion, chunking, and embedding. It also needs a vector store, a retriever, and an orchestration layer connected to the LLM.
Why Enterprise RAG Needs More Than a Chatbot Wrapper
Enterprise RAG must handle access control, multiple data sources, and document formats at scale. A demo chatbot skips all three.
The AI Model Is Ready. Your Business Data Is Still Out of Reach.
A generative AI model without access to your systems produces generic output. The gap between a demo and a working RAG application sits in the retrieval layer.
Generic Answers, No Business Context
A model without retrieval cannot answer questions about your product, customers, or operations. It produces confident answers that are wrong for your specific business.
Data Sits in Silos the Model Cannot Reach
Policies, contracts, and product data sit across SharePoint, Confluence, ERPs, and shared drives. No single system connects them for AI to use.
No Audit Trail for AI Responses
Compliance and legal teams need to know where an answer came from. Generic AI tools rarely show their source documents.
Search That Misses Intent
Keyword search returns documents, not answers. Employees still read ten pages to find one paragraph that matters.
Security and Data Residency Uncertainty
Sending sensitive data to a public AI tool without access controls creates real exposure risk. Enterprise RAG needs role-based permissions built in from day one.
Every Team Builds Its Own Retrieval Logic
Without a shared RAG layer, each team builds its own connection, chunking approach, and prompt logic. This creates duplicated effort and inconsistent answers.
RAG Development Services We Deliver
We provide custom RAG development services end to end, from architecture to production deployment. Each service below solves a specific enterprise knowledge problem.
-
We design and build custom RAG applications from data pipeline to user interface. Each application is scoped to your specific retrieval and response needs.
-
Enterprise RAG development covers multi-source data integration, access control, and scale. We build systems designed for thousands of concurrent enterprise users.
-
We turn scattered internal documents into a private, searchable knowledge base. Your data never leaves your controlled environment during retrieval.
-
We build AI assistants that answer employee and customer questions using your own documents. Every response cites the source passage it came from.
-
Document-grounded AI ties every generated answer back to a specific passage in your content. This reduces hallucination and builds user trust in the system.
-
We provide vector search development and semantic search solutions that understand meaning, not just keywords. Results improve even when a query is phrased loosely.
-
Our AI document retrieval connects structured and unstructured enterprise data, including databases and PDFs. Retrieval stays fast even as data volume grows.
-
Hybrid search implementation combines keyword and vector search for higher retrieval accuracy. This catches both exact terms and conceptual matches.
-
We build response systems that generate answers strictly from retrieved content. This keeps grounded AI responses accurate and verifiable for enterprise use.
-
Secure RAG architecture enforces role-based access at the retrieval layer, not just the application layer. Regulated industries get secure RAG solutions with a clear audit trail.
Where Enterprise RAG Solutions Create Business Value
RAG applications solve different problems depending on where they sit in the business. These are the use cases we build most often for enterprise AI knowledge management.
Enterprise Knowledge Management
RAG turns policy documents, SOPs, and internal wikis into instantly searchable knowledge. Employees get answers in seconds instead of searching shared folders.
AI-Powered Enterprise Search
Search across every connected system from one interface, ranked by relevance and meaning. Results improve as more content gets indexed over time.
Internal Knowledge Assistants
Give employees a single assistant for HR policies, IT procedures, and internal documentation. This reduces repetitive tickets sent to support teams.
Document Intelligence & Retrieval
Extract answers from contracts, invoices, and reports without manual review. Document intelligence and retrieval works across scanned and native file formats.
Secure AI Knowledge Systems
Deploy knowledge AI with encryption, access controls, and audit logging built in from the start. This meets the documentation requirements common in regulated industries.
AI-Powered Customer Support Knowledge
Ground support responses in your actual product documentation and help center content. Agents and self-service bots answer consistently from the same source.
Enterprise Data Question Answering
Ask questions in plain language and get answers pulled from structured and unstructured data. No SQL query or manual lookup is required.
RAG-Based Business Automation
Trigger workflows automatically when retrieval identifies a specific condition in a document. This connects knowledge retrieval to downstream business processes.
Industries That Benefit From Enterprise RAG Development
RAG development applies wherever teams need fast, accurate answers from large volumes of documentation. These are the industries where we see the clearest impact.
How We Deliver a RAG Development Engagement
We follow a structured process from data audit to production deployment. Every phase produces a specific, reviewable, and deliverable. We map your document sources, data formats, and access requirements before writing any code.
- 01
Data and Systems Audit
Our assessment of your data sources, systems, formats, and access requirements helps identifying the right RAG architecture.
This helps create a reliable foundation for accurate retrieval and seamless integration.
- 02
Technology Selection
The team of RAG architectures select the right LLMs, vector databases, embedding models, and RAG frameworks for your use case.
Our approach balances accuracy, scalability, performance, security, and operating costs.
- 03
Data Ingestion, Chunking, and Embedding
We prepare and structure your business data for efficient retrieval across documents, databases, APIs, and other sources.
Our team applies optimized chunking and embedding strategies to improve context quality and retrieval accuracy.
- 04
Retrieval and Orchestration Build
The expert’s technique to build retrieval pipelines assists in finding relevant context and delivering it to the LLM at the right time.
We connect retrieval, prompting, tools, and business workflows to produce grounded and useful responses.
- 05
Evaluation, Guardrails, and Security Testing
We test retrieval quality, response accuracy, hallucination risks, access controls, and data security before deployment.
Guardrails help keep responses relevant, safe, compliant, and aligned with your business rules.
- 06
Deployment, Monitoring, and Continuous Improvement
The RAG expert team deploys your solutions into your preferred cloud or enterprise environment with production-ready monitoring.
We continuously track performance, user feedback, retrieval quality, and model behavior to improve the system over time.
What Solutions Have We Offered So Far
See how our RAG development services turn enterprise data into accurate, context-aware AI experiences. Explore real-world implementations, from intelligent knowledge assistants to document-based AI systems and see how we connect LLMs with your business data to deliver measurable results.
Tools and Platforms Behind Our RAG Development Engagements
We select tools based on your existing stack and requirements, not a fixed template. These are the platforms we work with most.
OpenAI
Anthropic Claude
Google Gemini
Pinecone
Weaviate
Qdrant
Milvus
LangChain
LlamaIndex
SharePoint
Confluence
Google Drive
Amazon S3
RAG Implementation Challenges We Plan For
Most RAG failures come from a small set of recurring issues. We design these from the start, not after launch.
Hallucination and Ungrounded Answers
We constrain generation to retrieve content and add citation checks. Answers without sufficient supporting context are flagged instead of guessed.
Chunking and Retrieval Accuracy
Poor chunking causes irrelevant results even with a strong model. We tune chunk size and retrieval logic against your actual content.
Data Freshness
Static knowledge bases go stale fast. We build re-indexing pipelines, so retrieval reflects your latest documents automatically.
Multi-Format Documents
PDFs, scanned files, spreadsheets, and slide decks all need different parsing approaches. We handle format-specific extraction before indexing begins.
Latency at Scale
Retrieval speed can drop as your knowledge base grows. We optimize indexing and query paths to keep response times consistent.
Security and Access Control
Retrieval must respect existing permissions, not bypass them. We enforce role-based access at the retrieval layer, not only the interface.
What You Get with a Production RAG System
Answers Grounded in Your Own Data
Responses reference your actual documents instead of general model knowledge. Every answer can be traced back to its source.
Faster Access to Internal Knowledge
Employees stop searching for multiple systems for information that already exists. Retrieval replaces manual lookup across folders and tools.
Consistent Answers Across Teams
The same question gets the same grounded answer, regardless of who asks or when. This reduces reliance on tribal knowledge.
An Auditable Retrieval Trail
Every response can be traced to the documents it drew from. This supports compliance review and internal audit needs.
A System That Improves with Use
Retrieval quality improves as we tune it against real queries after launch. The system does not stay static after deployment.
Why Enterprises Choose Us for RAG Development
Full-Stack AI and Data Engineering Under One Roof
We handle data pipelines, model integration, and application development within one engineering team. This means you avoid coordinating multiple vendors on one build.
Cloud and Platform Partnerships
Our teams hold partnerships with AWS, Microsoft, and Google Cloud. This includes deployment, security hardening, and DevOps support for AI workloads.
Security and Compliance Experience
Our DevSecOps practice covers vulnerability testing and infrastructure hardening for client systems. That experience carries directly into secure RAG architecture, so security is built in, not bolted on.
FAQs
Ready to Ground Your AI in Your Own Data?
Every enterprise AI initiative eventually needs real data behind it. Start with a scoped assessment of your systems, documents, and retrieval requirements.
Ready when you are. Share which systems and documents your RAG application needs to connect to.