An enterprise team might create an AI chatbot to answer employee questions, develop an intelligent tool, or connect a large language model (LLM) to an internal knowledge base.
Although the differences may seem minor at first glance, they are significant from a business perspective. An AI prototype can accommodate manual processes, limited datasets, temporary infrastructure, and occasional errors. In contrast, a production application cannot rely on the original developer or assume that users will always provide clean inputs.
This is why Gen AI development company can make AI POC works. They should ask whether it is valuable, reliable, secure, scalable, maintainable, affordable, and ready to be owned by the business. So, when should an enterprise make the move?
The right time is when the POC has proved the business case and the organization has addressed the technical, operational, security, and governance requirements needed to support it in the real world.
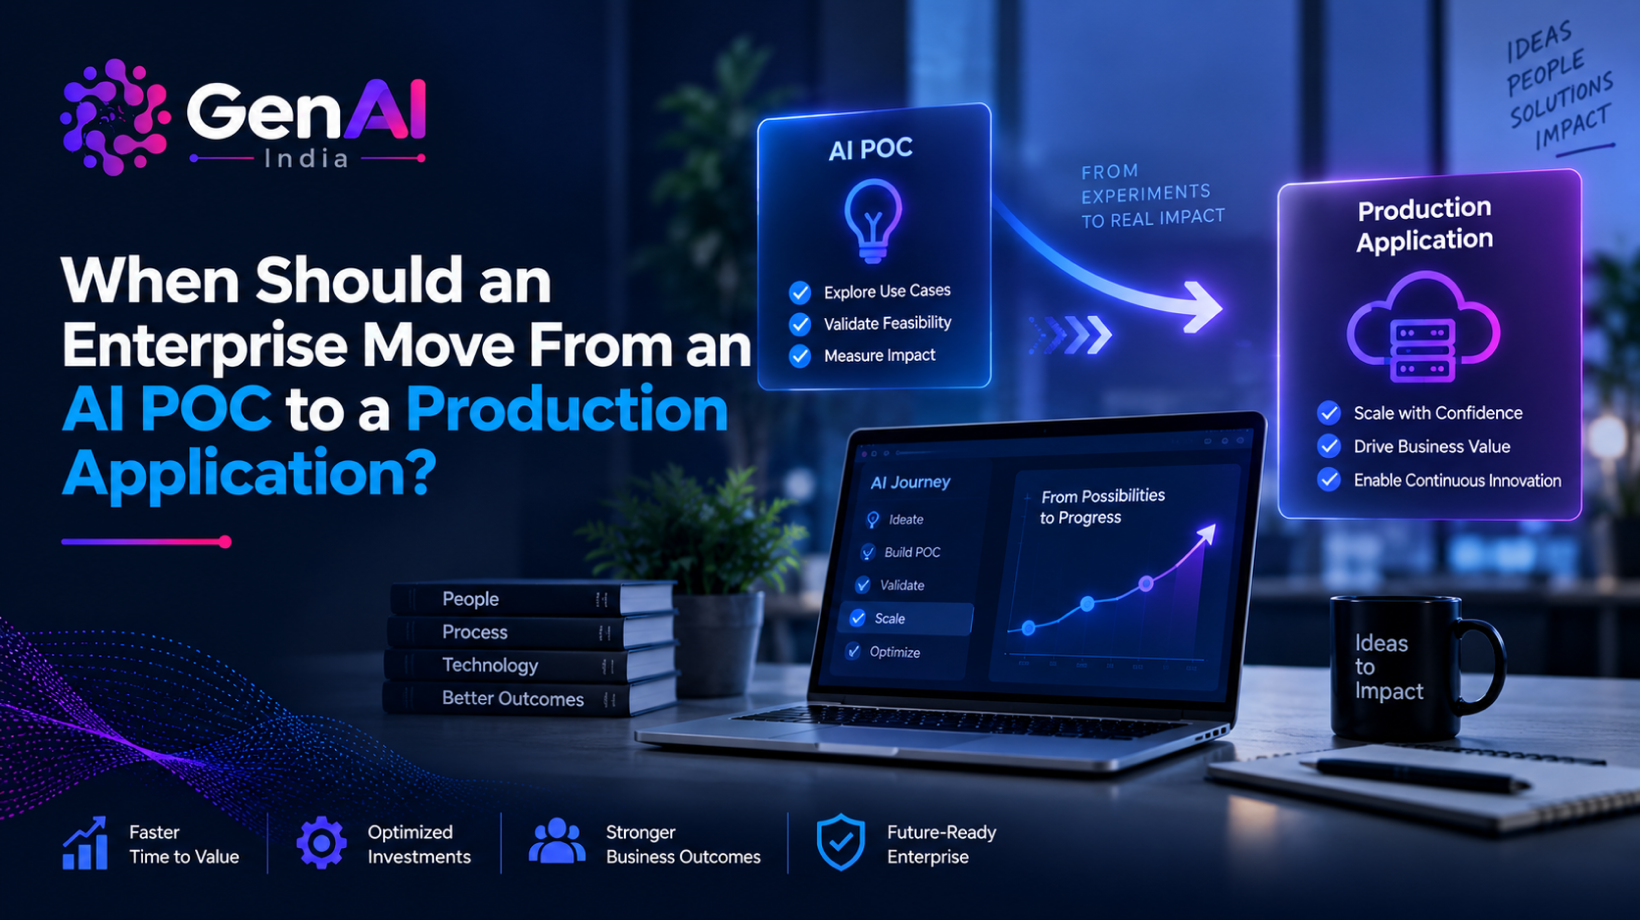
What Is an AI POC, and How Is It Different From a Production Application?
An AI proof of concept is essentially an experiment designed to determine whether a proposed AI solution is technically and commercially promising.
At this stage, a team may use a small dataset, a limited number of users, an experimental prompt, a third-party AI API, temporary cloud infrastructure, or even manual processes behind the scenes. That is not necessarily a problem. The purpose of a POC is to learn quickly without spending too much time and money building a complete product.
| Area |
AI POC |
Production AI Application |
| Primary goal |
Prove that the idea can work |
Deliver reliable business value at scale |
| Users |
Small test group |
Real employees or customers |
| Data |
Limited or curated data |
Real, continuous, production-quality data |
| Infrastructure |
Temporary or experimental |
Scalable and reliable infrastructure |
| Testing |
Basic validation |
Functional, security, performance, integration, and regression testing |
| Security |
Initial assessment |
Enterprise-level security and privacy controls |
| Scalability |
Limited user volume |
Designed for expected business demand |
| Cost |
Experimental budget |
Predictable and optimized operating costs |
| Monitoring |
Often limited |
Continuous technical and AI performance monitoring |
| Maintenance |
Developer-dependent |
Documented and maintainable by the engineering team |
| Governance |
Minimal |
Defined ownership, policies, and controls |
| Business KPI |
Potential value |
Measurable and ongoing business impact |
For example, a Gen AI chatbot development company might create a customer-support chatbot using an LLM and a small collection of product documentation. The chatbot answers 85% of test questions correctly, and the leadership team sees potential in it.
That is a good POC result.
But production raises very different questions.
A production AI application needs proper infrastructure, security, monitoring, testing, documentation, governance, cost controls, and ownership. Also hire Gen AI developer to understand and operate the system rather than depending entirely on its original creator.
Why Enterprises Should Not Move an AI POC to Production Too Quickly
AI creates a natural sense of urgency. When a prototype produces impressive results, business leaders may want to launch it immediately before competitors do. But moving too quickly can turn a promising experiment into an expensive operational problem.
A POC often operates within a carefully controlled environment. Developers know the test cases, understand the data, and manually handle unusual situations. Production removes many of those safeguards.
Real users ask unexpected questions. Data changes. Traffic increases. Integrations fail. Models behave differently with new inputs. API usage grows. Security threats become more relevant.
And a small error that was harmless during testing can become expensive when it affects thousands of customers. After production deployment, the company may process 50,000 complaints automatically. Now the question isn’t simply whether the AI can summarize complaints. It is whether the organization can detect incorrect summaries, measure their impact, identify patterns of failure, and intervene when necessary.
The First Question: Has the AI POC Proven a Real Business Problem?
Before worrying about infrastructure or model selection, ask a more fundamental question:
What business problem does this AI application solve?
This sounds obvious, but it is one of the most important questions enterprises can ask.
AI projects sometimes begin because a technology is exciting rather than because a business problem is significant. A team may build an AI assistant because generative AI is trending, even though employees do not have a meaningful problem that requires it. A technically impressive solution can still have little business value. The POC should have a measurable answer.
How to Easily Move From an AI POC to a Production Application?
Here are some easy steps to move to production application.
Step 1: Make Sure Your Data Is Ready for Production
Once the business case is validated, the next major question is data.
AI systems often look better during POC development because developers use carefully selected datasets.
It can contain outdated records, missing information, duplicate entries, inconsistent formats, biased examples, and unexpected inputs. If the AI application depends on enterprise data, these problems can directly affect its performance.
Step 2: Define What “Good Enough” Means for Your AI
Another common mistake is measuring AI success using one number. That sounds impressive, but accuracy alone does not tell a business whether the system is ready.
Consider a fraud detection system. If the model identifies fraudulent transactions accurately but produces so many false positives that legitimate customers are constantly blocked, the system may create more problems than it solves.
For an AI document-processing application, the focus could be extraction accuracy, processing time, manual-review rate, and cost per document.
Step 3: Test the AI With Real-World Inputs
A POC can be tested using predictable scenarios. Real users will ask incomplete questions, provide incorrect information, use unexpected language, change topics, and sometimes deliberately try to break the system.
Generative AI integration services introduce additional challenges because their outputs are probabilistic rather than completely deterministic.
That means enterprises should test not only successful scenarios but also failure scenarios.
Ask what happens when the AI does not know the answer.
- What happens when the user provides contradictory information?
- What happens when the input contains sensitive information?
- What happens when someone tries to manipulate the system?
- What happens when an external API becomes unavailable?
Step 4: Check Whether Your AI Architecture Can Handle Production Traffic
Enterprises should evaluate how the AI system will handle increased traffic, concurrent requests, data volume, API calls, and processing requirements.
The architecture include cloud services, databases, APIs, AI models, vector databases, data pipelines, authentication services, monitoring tools, and enterprise applications.
Each component introduces dependencies. The architecture should be designed around expected business usage, not simply around what was convenient for the POC.
Step 5: Ask Whether the POC Code Is Maintainable
One of the easiest ways to identify an immature AI POC is to ask:
“Could another developer take over this project tomorrow?”
If the answer is no, the system probably isn’t ready.
POCs are often built quickly. Developers experiment with libraries, prompts, APIs, scripts, and temporary configurations. That is normal.
Problems arise when the experimental code becomes the foundation of a production application without proper engineering.
Production code should have appropriate version control, testing, documentation, configuration management, error handling, logging, dependency management, and deployment processes.
The system should also be understandable without relying on the original developer’s memory.
Box UK’s production-readiness guidance makes a similar point: the system should be maintainable by developers who were not involved in the original prototype, rather than depending on the original developer or prompt history.
Step 6: Build a Production-Level Testing Strategy
Testing an AI application requires more than checking whether the model returns the expected answer. Security testing identifies vulnerabilities. Performance and load testing determine how the application behaves under realistic traffic.
Regression testing becomes especially important when prompts, models, data sources, or application logic change. Production AI therefore needs a repeatable evaluation process that can be run whenever significant changes are made.
This creates an important difference between traditional application testing and AI testing: the output quality itself may need continuous evaluation.
Step 7: Treat Security and Privacy as a Production Gate
An AI POC can sometimes operate using sample information. Production systems rarely have that luxury. The moment an AI application handles customer records, employee information, financial data, intellectual property, business documents, or other sensitive information, security becomes a major business concern.
Enterprises should understand exactly what information the AI system can access, where that information goes, who can access it, and how long it is retained. Generative AI systems also introduce risks such as prompt injection, data leakage, unauthorized tool usage, and inappropriate outputs.
Security testing should therefore be performed before launch rather than treated as a final checklist.
Step 8: Establish AI Governance Before You Go Live
Once an AI system becomes part of a business process, someone needs to own it. A production system needs clearly defined responsibility.
Someone should know who approves model changes, who monitors performance, who handles incidents, who manages vendors, and who decides when the AI needs to be retrained, replaced, or taken offline.
Governance becomes even more important when AI influences high-impact decisions involving customers, employees, finances, healthcare, legal matters, or access to services.
Good governance does not mean creating unnecessary bureaucracy.
It means creating enough structure that the organization knows who is responsible when the AI succeeds and, more importantly, when it fails.
Step 9: Calculate the Real Cost of Running AI in Production
One of the biggest surprises for enterprises is that the economics of a POC and production application can look completely different. Gen AI development costs can include model or API usage, security, engineering, support, maintenance, and ongoing model evaluation.
For generative AI applications, token consumption can also become a significant operational expense. The economics may be attractive. But if the AI costs $3 per request for a process that previously cost $1, the organization needs to rethink the architecture, model, workflow, or business case.
Cost optimization should therefore happen before production, not after the monthly cloud bill becomes a surprise.
Step 10: Build Monitoring and Observability Before Launch
Launching an AI application without monitoring is like running a business process without knowing whether it is working.
Production teams need visibility into both technical and AI-specific performance.
This can include response time, API failures, infrastructure usage, model errors, token consumption, cost, user feedback, and output quality.
For generative AI, enterprises may also want to monitor hallucination patterns, refusal rates, retrieval quality, and user corrections.
Step 11: Decide Where Human Oversight Is Necessary
AI doesn’t always need a human reviewing every output.
But high-risk use cases often benefit from human oversight.
For example, an AI system can identify potentially fraudulent transactions, but a human investigator may make the final decision.
An AI recruitment tool can summarize candidate information, but hiring decisions may remain with human managers.
An AI customer-service system can draft a response, while employees handle sensitive or unusual cases.
The idea is not to reduce AI’s value. It is to make sure the organization has a safety mechanism where mistakes could have significant consequences. The amount of human oversight should depend on the risk associated with the application. A low-risk internal brainstorming assistant may need very little human intervention.
Step 12: Prepare Employees and Customers for the AI Application
Even the most technically advanced AI system can fail if users don’t know how to use it. Employees need to understand what the system can do, what it cannot do, and when they should verify its output.
This is particularly important with generative AI because users may assume that confident-sounding answers are accurate.
Training should therefore cover practical usage rather than simply explaining how the technology works.
The 10 Signs Your AI POC Is Ready for Production
By this point, the decision becomes much clearer.
1. The Business Problem Is Clearly Defined
The application solves a meaningful problem rather than simply demonstrating an interesting AI capability.
2. The POC Has Demonstrated Measurable Value
There is evidence that the application can improve productivity, revenue, customer experience, efficiency, or another meaningful business metric.
3. Production Data Is Available
The AI can access reliable, representative, governed data rather than depending on a small experimental dataset.
4. Performance Meets an Acceptable Threshold
The enterprise has defined what acceptable AI performance looks like and tested the system against realistic scenarios.
5. The Architecture Can Scale
The infrastructure can support expected traffic, integrations, data volume, and availability requirements.
6. The Code Is Maintainable
Another qualified developer can understand, test, deploy, and modify the system without relying on the original creator.
7. Security and Compliance Risks Are Addressed
Data access, privacy, authentication, authorization, security testing, and regulatory requirements have been reviewed.
8. Production Costs Are Understandable
The organization knows the expected operating cost and understands whether the business case remains attractive at scale.
9. Monitoring and Ownership Are Defined
There is a clear owner and a mechanism for detecting performance, security, cost, or availability issues.
10. Users Are Ready
Employees, customers, or other users understand how to interact with the application and what to do when the AI produces an incorrect or uncertain response.
When Should an Enterprise Not Move an AI POC to Production?
Knowing when to stop is just as important as knowing when to proceed.
An enterprise should reconsider production deployment if the business value remains unclear. It should also pause if the AI depends on unreliable data, produces inconsistent results, creates unacceptable security risks, or costs more to operate than the value it generates.
The same applies when nobody clearly owns the system. A production application without an owner eventually becomes a neglected application.
Technical debt is another reason to pause. If the POC consists of scripts, undocumented configurations, manual steps, and code that only one developer understands, deploying it immediately may create a long-term maintenance problem.
There is nothing wrong with saying “not yet.” In fact, a controlled decision to improve the system before launch can save significantly more money than fixing a production failure later.
When Should Enterprises Bring in an AI Development Partner?
Not every organization needs external help to move a POC into production.
If an enterprise already has experienced AI engineers, cloud architects, data engineers, security specialists, and product teams, it may be able to handle the transition internally.
But there are situations where additional expertise can accelerate the process and reduce risk.
An internal team may understand the business problem extremely well but lack experience with MLOps or LLMOps. Another organization may have strong software developers but limited experience evaluating generative AI outputs. Others may need help designing scalable AI architecture, implementing monitoring, securing model integrations, or optimizing inference costs.
| Readiness Area |
Question to Ask |
Production-Ready Signal |
| Business value |
Does the AI solve a meaningful problem? |
Clear ROI or measurable business outcome |
| Data |
Is production-quality data available? |
Reliable, representative, governed data |
| Performance |
Does the AI meet required quality levels? |
Consistent results against defined benchmarks |
| Security |
Can sensitive information be protected? |
Security controls and risk assessment completed |
| Scalability |
Can it handle real-world usage? |
Infrastructure tested under expected load |
| Cost |
Is the solution financially sustainable? |
Predictable cost per user, request, or task |
| Code quality |
Can another developer maintain it? |
Documented, tested, version-controlled code |
| Monitoring |
Can problems be detected quickly? |
Alerts, logs, metrics, and AI evaluations in place |
| Governance |
Who owns the system? |
Clear business and technical ownership |
| User readiness |
Are users prepared to adopt it? |
Training, documentation, and feedback processes |
An experienced AI development partner can help bridge these gaps.
The important thing is to use external expertise for a clearly defined capability gap rather than outsourcing responsibility blindly.
The enterprise should still maintain ownership of the business objectives, data, governance, and final production decisions.
Conclusion:
A production-ready AI application needs more than an impressive model. It needs a validated business case, reliable data, measurable performance, scalable architecture, maintainable code, robust testing, appropriate security, clear governance, predictable costs, effective monitoring, and prepared users.
If the AI POC has demonstrated measurable value, performs reliably with realistic data, meets security requirements, can scale, has sustainable economics, and has clear operational ownership, the enterprise may be ready to take the next step. A POC proves that AI can work. Production proves that your business can trust, operate, measure, and scale it.
Want to Take Your AI POC to Production With An AI Expert?
Contact us
FAQs
1. When should an enterprise move an AI POC to production?
An enterprise should consider moving an AI POC to production when it has demonstrated measurable business value and the organization has validated data quality, AI performance, security, scalability, operating costs, maintainability, monitoring, governance, and user readiness.
2. What makes an AI POC production-ready?
A production-ready AI POC should solve a clearly defined business problem, perform reliably with realistic data, use maintainable code, integrate with enterprise systems, meet security and compliance requirements, support expected workloads, have predictable operating costs, and include monitoring and clear ownership.
3. What is the difference between an AI POC and a production AI application?
An AI POC is primarily designed to prove whether an idea is technically feasible and potentially valuable. A production AI application must operate reliably for real users and business processes. It therefore requires stronger engineering, security, scalability, monitoring, governance, testing, and support.
4. How long does it take to move an AI POC to production?
There is no universal timeline. A simple internal AI assistant may require a relatively short productionization cycle, while an enterprise AI system involving sensitive data, complex integrations, regulatory requirements, and large user volumes may require significantly more time. The timeline depends on the maturity and complexity of the POC.
5. What should be tested before deploying an AI application?
Enterprises should test functionality, AI output quality, data handling, integrations, security, performance, scalability, failure scenarios, and regression behavior. Generative AI applications should also be evaluated for issues such as hallucinations, prompt injection, inappropriate outputs, and sensitive-data leakage.
6. How much does it cost to move an AI POC to production?
The cost depends on the application’s complexity, model choice, data infrastructure, integrations, cloud environment, security requirements, monitoring needs, and expected usage.